ON THIS PAGE
Progress0%

Our Global Presence :




Model selection drives project cost: Foundation model APIs, fine-tuning, and training from scratch have significantly different cost, control, and implementation requirements.
A structured development lifecycle reduces risk: Use case definition, data preparation, model selection, integration, optimization, testing, deployment, and monitoring should be planned as connected stages.
RAG can connect AI to business knowledge: Retrieval-augmented generation helps applications work with proprietary information while supporting use cases such as enterprise research and knowledge retrieval.
Technology choices depend on the application: Python, PyTorch, TensorFlow, Hugging Face, vector databases, LangChain, Docker, Kubernetes, and cloud ML platforms can support different parts of the AI stack.
Generative AI costs vary by development approach: API-based applications are estimated at $10,000–$75,000, RAG applications at $50,000–$250,000, while training from scratch can reach millions of dollars.
Evaluation and human oversight are essential: Hallucinations, privacy risks, bias, integration complexity, and the limits of automation make testing, access controls, fallback workflows, and human review important implementation considerations.
Production AI requires ongoing monitoring: Generative AI applications need performance monitoring, retraining, and regular evaluation because usage patterns and edge cases can change after deployment.
Generative AI development has moved well past the demo stage, and the record now includes enough real outcomes to be honest about which projects paid off and which didn’t. Klarna’s OpenAI-built customer service assistant handled 2.3 million conversations in its first month live.
Morgan Stanley grounded a GPT-4 assistant in 100,000 internal research documents and got it in front of 98% of its advisor teams. Bloomberg spent an estimated $1 million to $3 million training a 50-billion-parameter model from scratch, and it still didn’t beat a general-purpose foundation model on the financial benchmark it was built for.
Three real deployments, three different lessons: sometimes the plan works exactly as designed, and sometimes it needs walking back a year later, or loses outright to a cheaper option instead.
This generative AI development guide is built around that spectrum. It covers the generative AI development lifecycle end to end, the technologies and programming languages teams actually reach for, what a project costs at each level of ambition, and where teams get it wrong, with sources attached to every claim rather than vendor talking points.
At Debut Infotech, we build generative AI solutions across finance and hospitality, and we’ve done the same kind of work in supply chain. Most of what determines whether a project succeeds gets decided in the first two weeks, in the choices covered below, long before a model ever gets trained or called.
Generative AI development is the process of building applications that create new content, text, code, images, audio, or structured data, rather than just classifying or predicting from existing data.
That’s the core distinction from traditional machine learning: a fraud-detection model tells you whether a transaction looks suspicious; a generative model can draft the email explaining why it was flagged.
Nearly all of that work happens on top of foundation models: large neural networks pretrained on massive datasets, which teams adapt rather than build from zero. There are three ways to do that adapting, and picking the wrong one is the single most expensive mistake a team can make.
Calling an existing foundation model like GPT or Claude through an API is fastest and cheapest, and the right starting point for most projects, since it puts application logic on top of a model someone else already trained and maintains.
Fine-tuning goes further: start from an open-weight foundation model and adjust its parameters on your own data, trading some speed for real control over domain-specific behavior. Training from scratch skips the foundation model altogether. It’s extremely expensive and rarely justified, worth understanding mainly through the case further down where it visibly didn’t pay off.
Large language models are the most common type of generative AI model in production today, but the field also covers image, audio, video, and code generation, increasingly through multimodal AI systems that handle more than one content type in a single model.
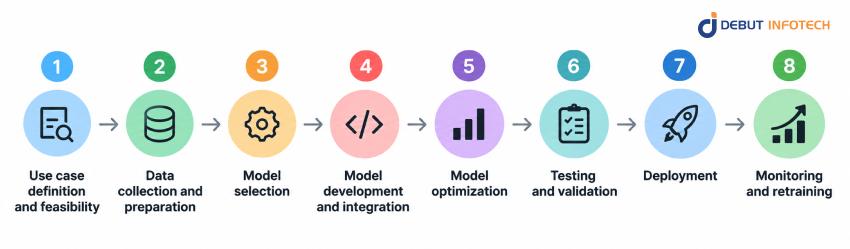
A generative AI development process step by step generally runs through eight stages, and skipping the first one is the most common reason projects stall later. It’s rarely a technology problem.
1. Use case definition and feasibility: Define the specific task the model needs to do and what “good enough” looks like before writing any code. Morgan Stanley scoped their assistant narrowly, retrieval over a defined research corpus, rather than a general-purpose chatbot, which made everything downstream simpler.
2. Data collection and preparation: Gather and clean the data the model will be grounded in or fine-tuned on. For retrieval-augmented generation (RAG), that means structuring a knowledge base the model can search accurately. Bad data here produces confident, wrong answers later, not an error message.
3. Model selection: Choose between an API-based foundation model, a fine-tuned open-weight model, or, rarely, training from scratch. This is where most budget mistakes happen, and the decision framework further down walks through it in detail.
4. Model development and integration: Build the RAG pipeline, prompt architecture, or fine-tuning job. Guardrails and citation logic belong here too, built in from the start rather than bolted on after something goes wrong.
5. Model optimization: Quantization and distillation shrink a model’s size and inference cost without a proportional drop in quality, which matters once you’re paying per token or per GPU-hour at real scale.
6. Testing and validation: Most teams underinvest here. Morgan Stanley built a dedicated evaluation framework to test every use case before deployment, treating it as the foundation of the whole project rather than a final check, a deliberate response to operating somewhere a wrong answer has real consequences.
7. Deployment: How to deploy generative AI models depends heavily on the path chosen in step 3. Calling a hosted API is simplest. Serving your own fine-tuned weights means GPU infrastructure and MLOps tooling. Either way, deployment needs access controls and usage monitoring, plus fallback logic for whatever the model can’t handle on its own.
8. Monitoring and retraining: Usage patterns shift and new edge cases surface constantly. Klarna’s own experience is the clearest public example of why this stage doesn’t end at launch: an assistant that looked like an unambiguous win in month one needed real correction a year later.
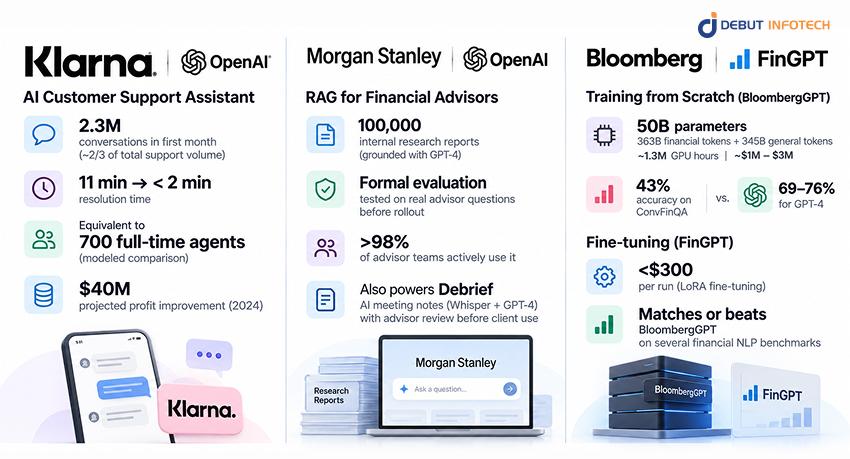
Klarna foundation model via API, and the year-later correction: Klarna’s OpenAI-built assistant launched in February 2024 and handled 2.3 million conversations in its first month, roughly two-thirds of the company’s total customer service volume, cutting resolution time from about 11 minutes to under 2.
Klarna described the workload as equivalent to 700 full-time agents, a modeled comparison rather than 700 literal layoffs, and projected a $40 million profit improvement for 2024. That’s the widely cited part of the story.
The part that matters more for anyone scoping something similar: in 2025, Klarna’s CEO told Bloomberg the company had leaned too hard into cost savings and that service quality had suffered for it.
Klarna was reopening hiring for more complex support roles as a direct result. The technology worked exactly as advertised for high-volume, low-complexity tickets. It was never a wholesale replacement for human judgment on the harder cases, and treating it as one is what forced the correction.
Morgan Stanley RAG in a regulated environment: Morgan Stanley partnered with OpenAI in 2023 to ground GPT-4 in roughly 100,000 of the firm’s own research reports, letting advisors query institutional knowledge in plain language instead of searching fragmented internal databases.
The firm built a formal evaluation framework to test the assistant against real advisor questions before rollout, the deliberate cost of operating somewhere an ungrounded answer isn’t a minor bug.
Today, over 98% of advisor teams actively use it, and the same approach now powers Debrief, a meeting-notes tool built on Whisper and GPT-4, still with an advisor reviewing outputs before anything reaches a client.
BloombergGPT vs. FinGPT; when training from scratch doesn’t win: Bloomberg trained a 50-billion-parameter model from scratch on 363 billion tokens of financial data and 345 billion tokens of general text, using roughly 1.3 million GPU hours, at an estimated cost of $1 million to $3 million.
On ConvFinQA, a financial question-answering benchmark, it scored 43% exact-match accuracy.
A general crowd of humans scored 47%. GPT-4, trained on none of Bloomberg’s proprietary data, scored between 69% and 76% zero-shot. FinGPT took the opposite bet: instead of training from scratch, it fine-tunes open-weight models with LoRA for under $300 per run, and on several financial NLP benchmarks it matched or beat BloombergGPT outright.
None of this is a knock on Bloomberg’s engineering. It’s the clearest publicly documented case of the step-3 decision playing out in the real world, worth sitting with before any team defaults to “we should train our own model” as a mark of ambition.
Python dominates the programming languages for generative AI development by a wide margin, carried by PyTorch and TensorFlow, with the Hugging Face ecosystem sitting on top of both. JavaScript and TypeScript do most of the work on the application layer, chat interfaces and API orchestration especially, with front-end integration rounding out the rest.
Some latency-sensitive inference work drops down to C++ or Rust underneath the Python-facing tooling.
Of the machine learning frameworks built on top of those languages, PyTorch is the current default for research and production alike; TensorFlow still has a strong footprint in older enterprise pipelines, and JAX shows up where a team needs heavy customization of the training loop itself.
For the models themselves, OpenAI’s GPT and Anthropic’s Claude are the two most widely used API-based foundation models, with Google’s Gemini close behind, while Meta’s Llama and Mistral’s models are the usual starting point for teams that want to fine-tune or self-host.
RAG-based applications, like Morgan Stanley’s, add a vector database to store and search embeddings, Pinecone and Weaviate are the most common choices, with Milvus and pgvector as options for teams already standardized on different infrastructure, and an orchestration framework like LangChain or LlamaIndex to handle the plumbing between the model and the database, feeding both into the application logic on top.
On the deployment side, Docker and Kubernetes cover containerization, and cloud-native ML platforms give teams managed infrastructure instead of running their own GPU clusters, AWS SageMaker and Google Vertex AI are the two most common, with Azure ML close behind.
The transformer architecture, introduced in 2017, underlies nearly every large language model in production today, including the models behind Klarna’s and Morgan Stanley’s assistants. Its core mechanism, self-attention, weighs the relevance of different parts of an input against each other, which is what lets a model track context across a long document or conversation.
Beyond transformers, the machine learning algorithms used in generative AI split by content type:
Which of these underlies a given tool matters less for most teams than the practical point from step 3: an off-the-shelf foundation model already embeds years of this research, and re-deriving it in-house is rarely where the value is.
Models generate plausible-sounding text whether or not it’s true. This is exactly why Morgan Stanley invested in a dedicated evaluation framework instead of treating testing as a formality.
The quieter risk. Fine-tuning or grounding a model on proprietary data creates real exposure, and teams need to know precisely what a model was trained on before that data can resurface in front of the wrong user.
The one that tends to surprise people most. Connecting a generative AI system to existing databases and business logic, CRMs included, is consistently harder and slower than building or calling the model itself. That pattern holds across every industry we’ve built for: the model is rarely the actual bottleneck.
Follows a related pattern. The BloombergGPT example above is the extreme case, but reaching for the most expensive, most impressive-sounding option when a cheaper one would do the job shows up at much smaller scale constantly.
Easy to underestimate precisely because a well-known foundation model feels like it should have already solved it. Models trained on historical data inherit historical patterns, biased ones included, and that needs active testing rather than an assumption.
Underneath all of it sits the gap Klarna’s 2025 correction made public: generative AI absorbs enormous volume on structured, repetitive tasks, but it still isn’t a substitute for judgment on the harder tail of cases, no matter how good the automation rate looks in month one.
The cost of generative AI development spans a wider range than almost any other software category, mostly because the three model-selection paths from step 3 sit orders of magnitude apart in price.
| Approach | Cost Range | Timeline | Notes |
| API integration (prompt engineering, no fine-tuning) | $10,000-$75,000 | 4-10 weeks | Fastest path; ongoing per-token costs scale with usage |
| RAG-based application (vector DB, retrieval pipeline) | $50,000-$250,000 | 8-16 weeks | The Morgan Stanley pattern; scales with data volume |
| Fine-tuning an open-weight model | $5,000-$100,000+ | 6-14 weeks | Highly variable; the FinGPT pattern |
| Training a model from scratch | $1M-$10M+ | 6-18+ months | Rarely justified; the BloombergGPT pattern |
| Ongoing maintenance and monitoring | 15-30% of build cost/year | Ongoing | Retraining, updates, monitoring infrastructure |
What actually moves a project between rows in that table isn’t just ambition, it’s a handful of concrete factors. Data volume and quality set the floor: clean, structured data lowers cost, while messy or siloed data turns into a data engineering project before the AI work even starts.
Model choice is the biggest single lever, since an API call costs orders of magnitude less than fine-tuning, which costs orders of magnitude less than training from scratch.
Integration depth matters just as much in practice: a standalone chatbot is cheap, but an assistant with write access into a CRM, a PMS, or a core banking system isn’t, mostly because of the access controls and testing that write access demands.
Regulatory requirements add their own cost, Morgan Stanley’s eval-framework investment is really the price of operating in a regulated industry, and a lower-stakes consumer app can usually ship with a lighter validation process.
And ongoing inference cost is the one teams forget to budget for: API-based models charge per token, so the bill scales with usage in a way a fixed-price fine-tuning project never does.
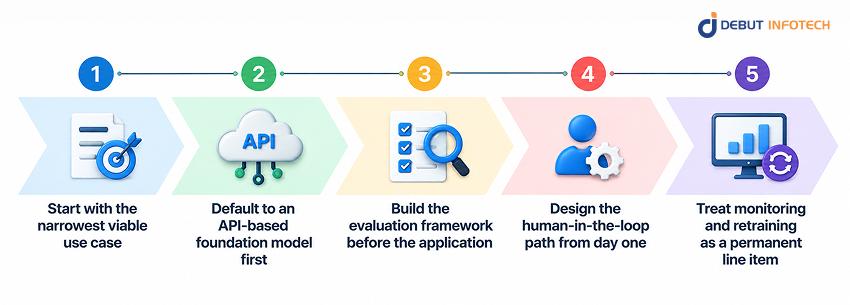
1. Start with the narrowest viable use case
Morgan Stanley’s assistant worked because it was scoped to retrieval over a defined research corpus, not “help advisors with everything.” A narrow scope makes every later decision simpler: what data to collect, how to evaluate correctness, and what counts as an edge case.
2. Default to an API-based foundation model first
Only move to fine-tuning or custom training once there’s a specific, demonstrated reason the foundation model can’t do the job. This is the single most consequential decision in the whole process, and the BloombergGPT case above is what it costs to get it wrong.
3. Build the evaluation framework before the application
Decide what “correct” looks like and how you’ll measure it before writing any integration code. Morgan Stanley built a dedicated evaluation framework to test every use case against real advisor questions before rollout, not as a final check but as the foundation of the project.
4. Design the human-in-the-loop path from day one
Decide now which outputs get reviewed by a person, rather than retrofitting oversight after a Klarna-style correction becomes necessary. This is a design decision, not a safety net bolted on afterward.
5. Treat monitoring and retraining as a permanent line item
Not a one-time deployment cost. Usage patterns shift and new edge cases surface constantly, and an assistant that looks like an unambiguous win in month one can need real correction a year later, exactly what happened at Klarna.
The thread running through all five steps is the same one this guide keeps returning to: the decisions that determine whether a project succeeds get made before a model is ever trained or called, and steps 1 through 4 above are where that happens.
Foundation Model via API: the default for most projects
Fine-Tuning: earns its cost under specific conditions
Training From Scratch: rarely justified
That combination describes a small number of frontier AI labs. It very rarely describes an enterprise application team, and the honest move in almost every case is to rule this path out early rather than let ambition make the decision.
Questions to Ask Before Signing
Warning Signs to Watch For
We’ve built generative AI solutions across financial services and hospitality, with supply chain work alongside that, which means we’ve made this exact model-selection call, API versus fine-tuning versus, almost never, training from scratch, across a real range of budgets and regulatory environments, not just once in a case study.
Our generative AI development services start with use case scoping and feasibility, before any code gets written, because that’s the stage this guide keeps coming back to as the one that actually determines outcome.
From there it’s RAG architecture and vector database integration where retrieval fits the problem, and fine-tuning on proprietary data where that’s genuinely the right call rather than the impressive-sounding one.
An evaluation framework gets built in from the start too, so testing happens before launch instead of after something’s already gone live, and monitoring and retraining are part of the build itself, not a line item we add once a client asks why performance has drifted.
If you’re earlier in the process and still deciding whether any of this is worth pursuing, that scoping conversation is exactly where we’d start anyway, no build required to have it.
Define a narrow, specific use case rather than a general-purpose one. Default to an API-based foundation model unless there’s a demonstrated reason to fine-tune or, rarely, train from scratch.
Build the evaluation framework before the integration code, and design human review into the workflow for any output reaching an end user unchecked. Treat retraining as ongoing too, not a one-time step.
It runs through a lifecycle: defining the use case, collecting and preparing data, selecting a model approach, building the integration, optimizing for cost and latency, testing against real-world cases, deploying to production, then monitoring and retraining continuously.
Most projects build on pretrained foundation models rather than training new ones, since those models already encode most of the language and reasoning capability a project needs.
API-based foundation models deploy through the provider’s API, the simplest path. Fine-tuned or self-hosted models need GPU infrastructure, either your own or a managed cloud platform, plus containerization and MLOps tooling for versioning and monitoring.
Either way, deployment needs access controls and usage monitoring, with a clear fallback path for cases the model handles poorly.
Hallucination and factual accuracy, data privacy when models are grounded or fine-tuned on proprietary data, integration complexity that usually outweighs the model work itself, cost overruns from choosing a more ambitious approach than the use case needs, inherited bias, and the ongoing gap between automating routine cases and replacing human judgment on complex ones, the lesson behind Klarna’s 2025 correction.
Simple API integration runs $10,000 to $75,000. RAG-based applications run $50,000 to $250,000. Fine-tuning an open-weight model ranges from $5,000 to over $100,000.
Training from scratch runs into the millions, BloombergGPT cost an estimated $1-3 million, and is rarely the right call for an enterprise application. Ongoing maintenance typically adds 15-30% of build cost per year.
Data volume and quality, the model approach chosen, integration depth into existing systems, regulatory requirements that demand a more rigorous evaluation framework, and ongoing inference costs that scale with usage for API-based approaches.
Python, built on PyTorch and TensorFlow, is the dominant language. Foundation models come from OpenAI and Anthropic as API-based options, or as open-weight models like Llama and Mistral, with Google’s Gemini rounding out the major API providers.
RAG applications add a vector database and an orchestration framework like LangChain. Deployment relies on Docker and Kubernetes, plus managed platforms like AWS SageMaker or Vertex AI.
Vector databases for retrieval, orchestration frameworks like LangChain and LlamaIndex to connect models to data and application logic, evaluation and monitoring tools to test outputs before and after launch, and MLOps platforms to manage deployment and versioning. The tool stack should follow from the model approach chosen in step 3, not the other way around.
Our Latest Insights
USA

2501 Chatham, Rd Suite R Springfield, IL 62704
+1-708-515-4004
info@debutinfotech.com
UK

7 Pound Close, Yarnton, Oxfordshire, OX51QG
+44-770-304-0079
info@debutinfotech.com
Canada

154 Eden Oak Trail, Kitchener, ON N2A 0H9
+1-708-515-4004
info@debutinfotech.com
INDIA

Sector 101-A, Plot No: I-42, IT City Rd, JLPL Industrial Area, Mohali, PB 140306
9888402396
info@debutinfotech.com

9001:2015
Quality Certified

ISO 27001
Security Certified

A+ Rating
Accredited Business

Certik
Security & Audit


Copyright © 2026, Debut Infotech. All rights reserved. | Privacy Policy